 openai /
gpt-6.2-astra
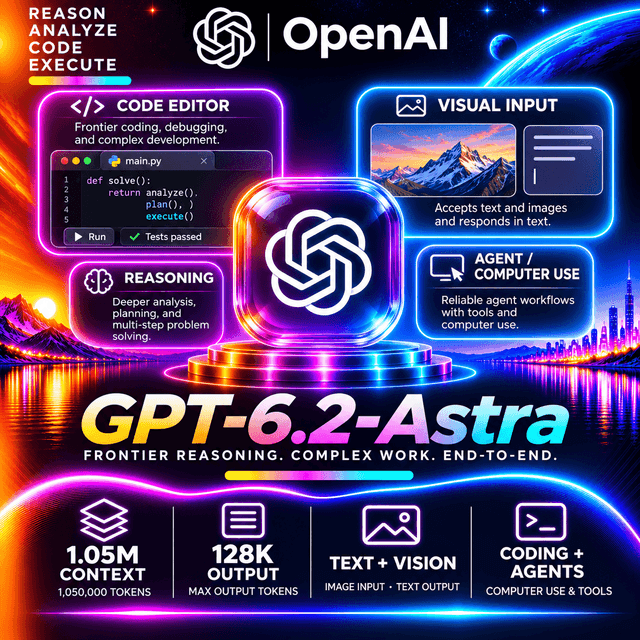
OpenAI's frontier model for professional and research work. Reads text, images and PDFs; returns text across a window of over a million tokens. Reasoning is always on with four effort levels and cannot be disabled; the deliberation itself is hidden and only its token count is reported. Tool calling runs on the Responses endpoint; Chat Completions covers everything else.

- Tools
- Vision
- PDF input
- Reasoning
- Structured output
- Reasoning
- Always on
reasoning_effort- low
- medium
- high
- xhigh
Use gpt-6.2-astra in VS Code, Cursor and Antigravity
DEVUP Code, the DEVUP AI extension, is free to install. Requests are paid from your DEVUP balance.
gpt-6.2-astra
gpt-6.2-astra is OpenAI's frontier model, built for professional and research work: complex coding, scientific analysis, agentic workflows, and long documents. It reads text, images and PDFs, and writes text.
It reasons before answering, and does so unusually economically — on a five-constraint logic puzzle with no valid solution, it proved the contradiction and said so rather than inventing an ordering, spending well under a hundred tokens of deliberation to get there.
At a glance
| Input | Text, images, PDF |
| Output | Text |
| Maximum context size | 1,048,576 tokens |
| Maximum output | 128,000 tokens |
| Reasoning | Always on, four effort levels, cannot be disabled |
| Tool calling | On the Responses endpoint only |
| Released | 17 November 2026 |
Maximum context size counts input and output together.
Getting started
curl https://api.devupai.com/v1/chat/completions \
  -H "Authorization: Bearer $DEVUP_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "openai/gpt-6.2-astra",
    "messages": [
      { "role": "user", "content": "Derive the time complexity of this algorithm and say where it degrades." }
    ]
  }'
Python, using the OpenAI client:
from openai import OpenAI
import os

client = OpenAI(
    api_key=os.environ["DEVUP_API_KEY"],
    base_url="https://api.devupai.com/v1",
)

response = client.chat.completions.create(
    model="openai/gpt-6.2-astra",
    messages=[
        {"role": "user", "content": "Derive the time complexity of this algorithm and say where it degrades."}
    ],
)

print(response.choices[0].message.content)
Node.js:
import OpenAI from "openai";

const client = new OpenAI({
  apiKey: process.env.DEVUP_API_KEY,
  baseURL: "https://api.devupai.com/v1",
});

const response = await client.chat.completions.create({
  model: "openai/gpt-6.2-astra",
  messages: [
    { role: "user", content: "Derive the time complexity of this algorithm and say where it degrades." },
  ],
});

console.log(response.choices[0].message.content);
Tool calling
Tools work on /v1/responses. They are refused on /v1/chat/completions.
This is the one thing to know before building on this model. A chat-completions request carrying tools comes back as:
{
  "error": {
    "message": "This model does not accept reasoning_effort together with tools on /v1/chat/completions. Set reasoning_effort to \"none\", remove the tools, or use /v1/responses.",
    "code": "unsupported_parameter"
  }
}
The message offers three ways out, and only one of them works here. Setting reasoning_effort to none is not available — this model rejects that value (see Reasoning below). Omitting reasoning_effort entirely does not help either. Use the Responses endpoint.
curl https://api.devupai.com/v1/responses \
  -H "Authorization: Bearer $DEVUP_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "openai/gpt-6.2-astra",
    "input": "What is the weather in Oran?",
    "max_output_tokens": 256,
    "tools": [{
      "type": "function",
      "name": "get_weather",
      "description": "Current weather for a city",
      "parameters": {
        "type": "object",
        "properties": { "city": { "type": "string" } },
        "required": ["city"]
      }
    }]
  }'
The call comes back in the output array:
{
  "type": "function_call",
  "name": "get_weather",
  "arguments": "{\"city\":\"Oran\"}",
  "call_id": "call_WteDvgHCbO2CsR6cqImkpbBZ",
  "status": "completed"
}
Note the shape difference from Chat Completions: on Responses, a tool's name, description and parameters sit at the top level of the entry, not nested under a function key.
response = client.responses.create(
    model="openai/gpt-6.2-astra",
    input="What is the weather in Oran?",
    max_output_tokens=256,
    tools=[{
        "type": "function",
        "name": "get_weather",
        "description": "Current weather for a city",
        "parameters": {
            "type": "object",
            "properties": {"city": {"type": "string"}},
            "required": ["city"],
        },
    }],
)

for item in response.output:
    if item.type == "function_call":
        print(item.name, item.arguments)
Everything else — plain completions, images, PDFs, JSON output, streaming — works normally on Chat Completions. Tools are the single exception.
Reasoning
Deliberation is always on and cannot be switched off. Effort is set through reasoning_effort:
| Level | Behaviour |
|---|---|
low | Short deliberation |
medium | Balanced |
high | Extended deliberation |
xhigh | Maximum deliberation |
curl https://api.devupai.com/v1/chat/completions \
  -H "Authorization: Bearer $DEVUP_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "openai/gpt-6.2-astra",
    "reasoning_effort": "xhigh",
    "max_completion_tokens": 4000,
    "messages": [
      { "role": "user", "content": "Prove or disprove: every connected graph with n vertices and n edges contains exactly one cycle." }
    ]
  }'
What is not available
none, minimal and max are all rejected with HTTP 400, as is any unrecognised value. Code written against another reasoning model that sends reasoning_effort: "none" for cheap mechanical work will fail here, and there is no equivalent — this model always deliberates.
The deliberation is hidden
Reasoning text is not returned. The response reports how many reasoning tokens were spent, in usage.completion_tokens_details.reasoning_tokens, and nothing more.
response = client.chat.completions.create(
    model="openai/gpt-6.2-astra",
    reasoning_effort="high",
    messages=[{"role": "user", "content": "Why does this query plan do a full scan?"}],
)

print(response.usage.completion_tokens_details.reasoning_tokens)
print(response.choices[0].message.content)
Effort scales, from a very low base
Measured on the same logic puzzle, medium spent 10 reasoning tokens and xhigh spent 72 — the levels are graded, but the absolute volume is small compared with models that think in thousands of tokens. Terse deliberation is not the same as shallow deliberation: at xhigh, those 72 tokens were enough to establish that the puzzle's constraints were mutually contradictory and report that, instead of producing a plausible-looking but wrong answer.
Treat the levels as a real dial, and raise it for multi-step proofs, long planning chains and difficult debugging — but do not read a low token count as the model skipping the work.
Budget for deliberation
Reasoning tokens come out of the output budget and are spent before the answer. A tight max_completion_tokens can therefore end a request before any content is produced, returning finish_reason: "length" with empty content. Since reasoning cannot be turned off, the only lever is a budget large enough for both.
Images
Images are passed as image_url content parts.
curl https://api.devupai.com/v1/chat/completions \
  -H "Authorization: Bearer $DEVUP_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "openai/gpt-6.2-astra",
    "messages": [{
      "role": "user",
      "content": [
        { "type": "text", "text": "Which panel in this dashboard contradicts the others?" },
        { "type": "image_url", "image_url": { "url": "https://example.com/dashboard.png" } }
      ]
    }]
  }'
A data URI works in place of a hosted link:
{ "type": "image_url", "image_url": { "url": "data:image/png;base64,iVBORw0KGgo..." } }Several images can appear in one message, each as its own content part — useful for before-and-after comparisons and for a document sent page by page.
PDF documents
PDF files are passed as file content parts, so a document goes in whole.
import base64

with open("spec.pdf", "rb") as f:
    pdf_b64 = base64.b64encode(f.read()).decode()

response = client.chat.completions.create(
    model="openai/gpt-6.2-astra",
    max_completion_tokens=8000,
    messages=[{
        "role": "user",
        "content": [
            {"type": "text", "text": "Which requirements in this spec conflict with each other?"},
            {"type": "file", "file": {
                "filename": "spec.pdf",
                "file_data": f"data:application/pdf;base64,{pdf_b64}",
            }},
        ],
    }],
)
A long PDF consumes a large share of the window, and pushes the request toward the long-context billing band described below. Send the sections that matter rather than an entire archive.
Structured output
Both json_object and json_schema are accepted. Prefer json_schema with strict: true — it constrains the shape rather than merely requesting it.
curl https://api.devupai.com/v1/chat/completions \
  -H "Authorization: Bearer $DEVUP_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "openai/gpt-6.2-astra",
    "max_completion_tokens": 4000,
    "messages": [
      { "role": "user", "content": "From this incident note, extract the service, severity and first-seen time: checkout-api, SEV2, first seen 2026-11-18T09:14Z." }
    ],
    "response_format": {
      "type": "json_schema",
      "json_schema": {
        "name": "incident",
        "strict": true,
        "schema": {
          "type": "object",
          "properties": {
            "service": { "type": "string" },
            "severity": { "type": "string" },
            "first_seen": { "type": "string" }
          },
          "required": ["service", "severity", "first_seen"],
          "additionalProperties": false
        }
      }
    }
  }'
Leave room in max_completion_tokens for the deliberation that precedes the object. A truncated reply is also invalid JSON, so check finish_reason before parsing.
For high-volume mechanical extraction, consider whether this model is the right tool at all: it is built for hard problems, it always reasons, and a smaller model will do field-mapping work at a fraction of the cost.
Streaming
stream = client.chat.completions.create(
    model="openai/gpt-6.2-astra",
    messages=[{"role": "user", "content": "Walk through how a write-ahead log recovers after a crash."}],
    stream=True,
)

for chunk in stream:
    delta = chunk.choices[0].delta
    if delta.content:
        print(delta.content, end="", flush=True)
Because deliberation is hidden, nothing streams while the model is thinking — the stream stays silent, then the answer arrives. Show a waiting state rather than an empty response area, and expect the silence to lengthen as effort rises.
Prompt caching
A repeated opening section of a conversation is served from cache at the cached-input rate. The rule is simple: stable content first, variable content last.
messages = [
    {"role": "system", "content": LONG_SYSTEM_INSTRUCTIONS},   # unchanged every call
    {"role": "user", "content": REFERENCE_DOCUMENTS},          # unchanged every call
    {"role": "user", "content": todays_question},              # changes
]
The cache matches on an exact prefix. One edited character near the top invalidates everything after it, so anything that varies — a timestamp, a user ID, a request counter — belongs at the end, never in the system message.
Long context and its billing band
The window holds over a million tokens across input and output combined, with output capped at 128,000.
A request whose input passes 272,000 tokens moves into a long-context band, and the higher rates apply to the whole request, not only to the tokens above the line. Input and cached input are charged at double the standard rate there; output at one and a half times.
Two consequences worth designing around:
- A request just over the line costs far more than one just under it. Splitting a 300,000-token job into two smaller calls can be cheaper than sending it whole, even counting the duplicated preamble.
- Retrieval beats stuffing. Sending the right fifty thousand tokens keeps the request in the standard band and usually produces a better answer than sending everything.
Images and PDFs count toward the same input total, so a few large documents can cross the threshold without any long text in the prompt.
Choosing settings
| Task | Suggested configuration |
|---|---|
| Everyday analysis and drafting | reasoning_effort: "medium" |
| Proofs, planning chains, hard debugging | reasoning_effort: "xhigh", generous max_completion_tokens |
| Agent loops and tool use | /v1/responses with tools |
| Machine-readable results | response_format with json_schema, strict: true |
| Screenshots, charts, diagrams | image_url parts |
| Specifications, contracts, reports | file parts with a PDF |
| Repeated long preambles | Stable content first, variable content last |
| Inputs near 272,000 tokens | Split the request, or retrieve rather than send everything |
Common pitfalls
| Symptom | Cause | Fix |
|---|---|---|
unsupported_parameter when sending tools | Tools are refused on Chat Completions for this model | Use /v1/responses |
HTTP 400 on reasoning_effort | none, minimal and max are not valid here | Use low, medium, high or xhigh |
| Code ported from another model fails immediately | It sends reasoning_effort: "none" | There is no off switch; use low |
Empty reply, finish_reason: "length" | Deliberation consumed the output budget | Raise max_completion_tokens |
| Invalid JSON from a schema request | Same cause — the object was cut off | Check finish_reason before parsing |
| No reasoning text in the response | Deliberation is hidden by design | Read reasoning_tokens for the count |
| A bill far larger than expected | The request crossed the 272,000-token input threshold | Split the request or retrieve less |
| Nothing streams for several seconds | The model is thinking, and thinking is not streamed | Show a waiting state |
Limits to keep in mind
Like any model of this kind, gpt-6.2-astra can state something false with confidence, miss part of a precise instruction, and lose coherence over very long multi-turn exchanges. Quality varies across languages and domains, and its knowledge ends at its training cutoff.
It is a frontier model priced accordingly, and it always reasons. That combination makes it a poor fit for high-volume simple work — classification, formatting, routing, bulk extraction — where a smaller model is both cheaper and faster. Reach for it when the problem is genuinely hard.
For consequential work, measure it on your own task before relying on it, add checks in your application, and keep a person in the loop.
References
- Introducing GPT-6.2 Astra and Sol — the release announcement.


