Model Library
Browse and deploy state-of-the-art AI models through the DEVUP Gateway.
Loading models...
Model Library
Browse and deploy state-of-the-art AI models through the DEVUP Gateway.
Browse and deploy state-of-the-art AI models through the DEVUP Gateway.
e5-large-v2 is an open-source text embedding model developed by Microsoft Research. Based on a 335-million parameter BERT-large encoder architecture, it maps text into a dense 1024-dimensional vector space using weakly-supervised contrastive pre-training followed by supervised fine-tuning. It utilizes asymmetric prefix conditioning ("query: " and "passage: ") to optimize dense retrieval and semantic search, delivering strong zero-shot retrieval accuracy across diverse domains with predictable inference latency.
e5-base-v2 is an open-source text embedding model developed by Microsoft Research. Based on a 109-million parameter BERT architecture, it is pre-trained using weakly-supervised contrastive learning. It generates 768-dimensional dense vectors and requires specific text prefixes ("query: " and "passage: ") to distinguish between search intents and document indexing, offering a strong balance between high retrieval accuracy and minimal computational cost for semantic search and RAG applications.
bge-m3-multi is an alternative designation for the bge-m3 embedding model developed by the Beijing Academy of Artificial Intelligence (BAAI). Built on a 567-million parameter XLM-RoBERTa architecture, the "Multi" suffix emphasizes its core design pillars: Multi-Linguality (supporting over 100 languages), Multi-Functionality (simultaneous Dense, Sparse, and Multi-Vector ColBERT outputs), and Multi-Granularity (handling inputs up to 512 tokens). It serves as a unified, state-of-the-art engine for hybrid search and complex multilingual Retrieval-Augmented Generation (RAG) pipelines.
bge-m3 is a state-of-the-art multi-lingual, multi-functionality, and multi-granularity text embedding model developed by the Beijing Academy of Artificial Intelligence (BAAI). Built on a 567-million parameter XLM-RoBERTa architecture, it supports over 100 languages and processes input sequences up to 8,192 tokens. It is uniquely engineered to output dense embeddings, lexical/sparse weights (similar to SPLADE), and multi-vector representations (ColBERT-style) simultaneously within a single forward pass, making it a foundational engine for versatile hybrid search and RAG systems.
bge-large-en-v1.5 is a high-performance open-source text embedding model developed by the Beijing Academy of Artificial Intelligence (BAAI). Built on a 335-million parameter BERT-large encoder architecture, it maps text into a dense 1024-dimensional vector space optimized for semantic search, retrieval-augmented generation (RAG), and zero-shot ranking. Version 1.5 improves similarity score distribution and delivers top-tier performance across the Massive Text Embedding Benchmark (MTEB) while balancing embedding accuracy with practical inference latency.
bge-en-icl is a 7.11 billion parameter large language model-based embedding model developed by the Beijing Academy of Artificial Intelligence (BAAI), built upon the Mistral-7B backbone. It introduces powerful in-context learning (ICL) capabilities to text embedding generation, allowing users to provide task-specific examples (few-shot prompts) alongside their queries. This eliminates the need for fine-tuning for new tasks while achieving state-of-the-art retrieval and semantic representation performance on benchmarks like MTEB and AIR-Bench.
bge-base-en-v1.5 is an open-source text embedding model developed by the Beijing Academy of Artificial Intelligence (BAAI). Built upon a 109-million parameter BERT-base encoder architecture, it maps text into a dense 768-dimensional vector space optimized for semantic search, dense retrieval, and Retrieval-Augmented Generation (RAG) pipelines. Version 1.5 refines similarity score distributions and delivers top-tier performance on the Massive Text Embedding Benchmark (MTEB) while maintaining extremely low latency and hardware requirements.
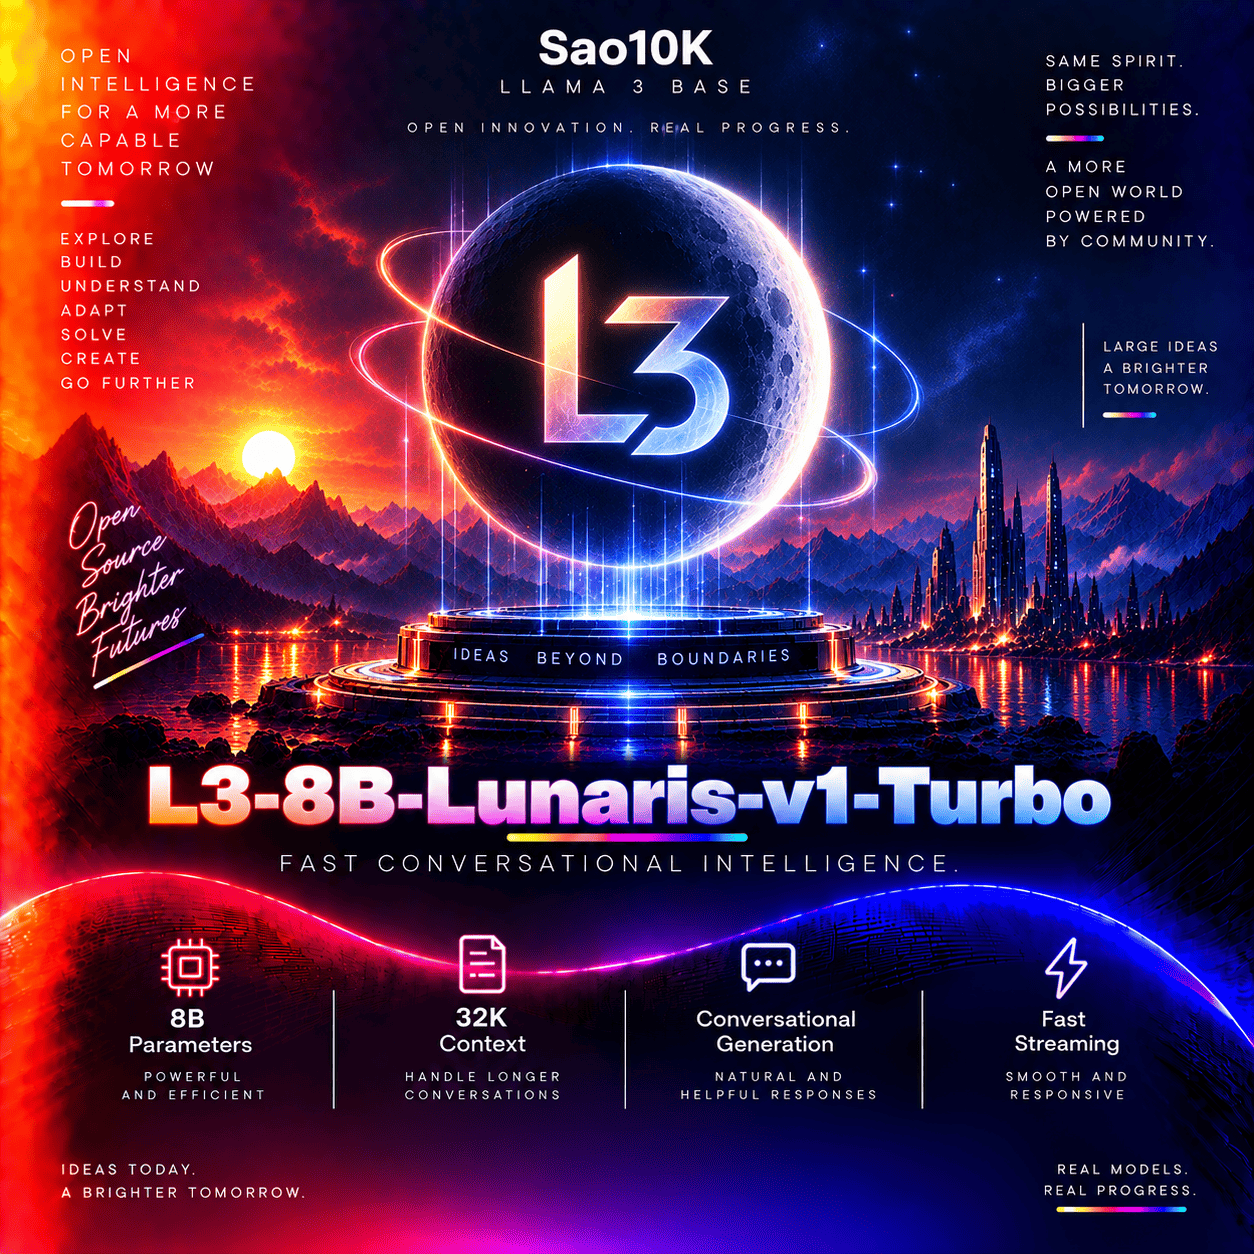
Lunaris is a merge of five Llama 3 models, made by one person, with the full recipe published — every source model, every density, every weight. Its creator describes the method candidly as black box magic, with values arrived at through years of personal experimentation rather than theory. It is built for roleplay and creative writing, and the recommended sampling reflects that: temperature 1.4, roughly ten times what most models in this catalogue suggest, held in check by a min-p floor that keeps the variance inside coherent choices. An 8,192-token window, and a model that reportedly holds its own against much larger ones at its task.
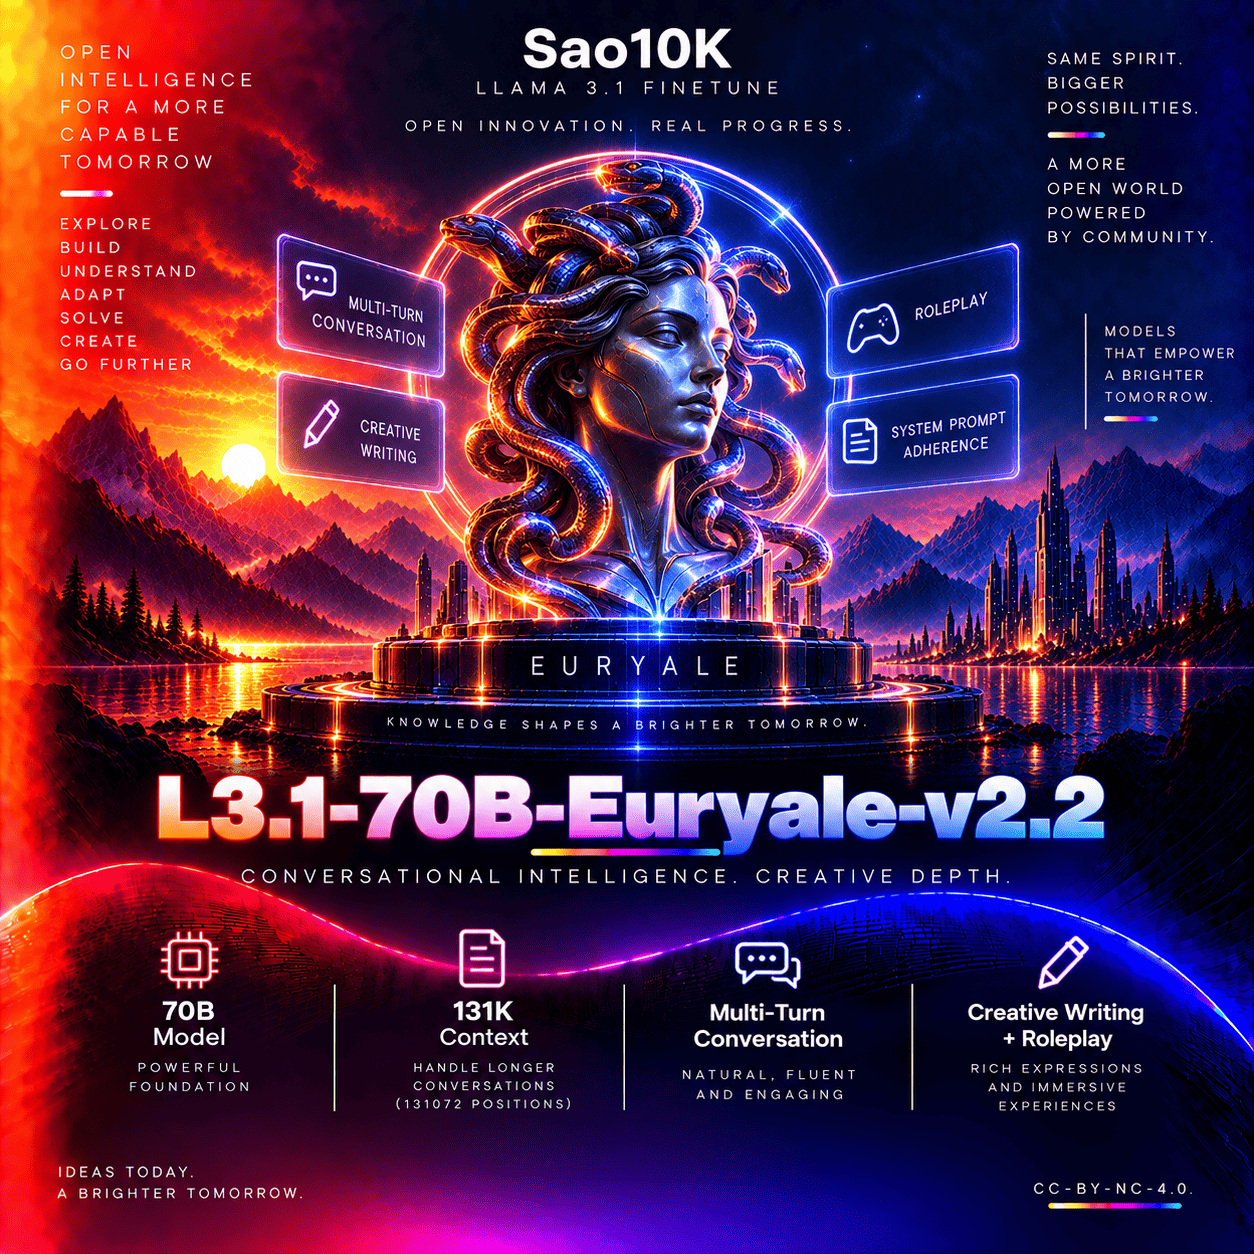
Euryale v2.2 is a trained creative model rather than a merge, built on Llama 3.1 70B by the same creator as the Lunaris merge — and the difference in method shows in what it improved. Its stated gains are multi-turn coherency, system prompt handling, and reasoning: precisely the three things that break first in a long collaborative fiction session, when a model forgets who it is playing, drifts from the scene you defined, and contradicts what happened an hour ago. Seventy billion parameters with a 131,072-token window, aimed at immersive storytelling with strong prompt adherence.
Qwen3.8-27B is a dense vision-language model that thinks before it answers — and by default, it thinks a great deal. Reasoning runs at the deepest of three settings unless you change it, which on long-form work can consume an entire output budget before a single word of the answer appears. The three levels turn out to be three system prompts rather than three capability tiers: one asks the model to deliberate, one says nothing, one asks for brevity. Independent measurement across ninety-six runs found no quality difference on short verifiable tasks. Sixty-four layers, three quarters of them linear attention, with a 262,144-token window and hour-scale video understanding.
Muse Glimmer 30B is Meta Superintelligence Lab's first open-weight release, and it was designed around a single constraint: an agent that runs on the machine in front of you. Roughly 29.6 billion dense parameters including a dedicated vision encoder, distilled from a larger model, and quantized to fit under 20 GB — small enough to run on one consumer GPU while still holding a 131K context and reading screenshots, charts, and documents. What sets it apart is what it was trained for rather than what it knows: sustained tool use across long workflows, and diagnosing a failed tool call and retrying rather than stopping. It ships with published prompt-injection and privacy evaluations, which few models of any size do. Apache 2.0.
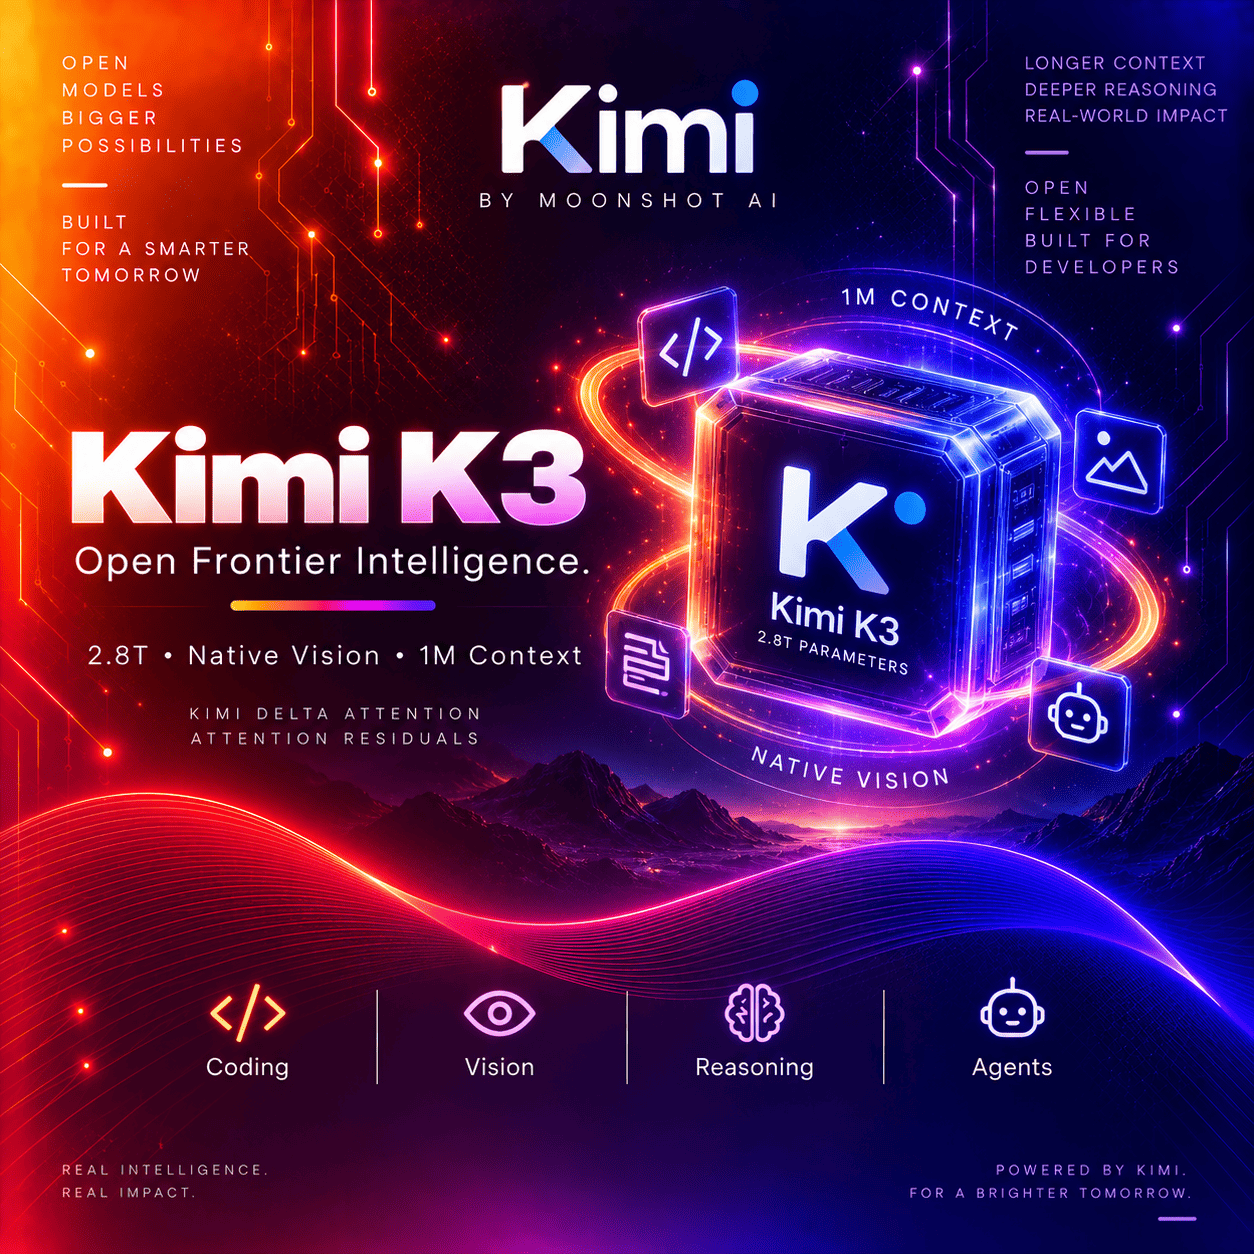
Kimi K3 is the first open model in the three-trillion-parameter class — 2.8 trillion total, 104 billion active, a million tokens of context, and native vision. Two architectural bets carry it: Kimi Delta Attention paired with Attention Residuals, and a sparsity framework that selects sixteen experts from eight hundred and ninety-six, together delivering roughly two and a half times the scaling efficiency of the previous generation. Thinking is permanently on with three effort levels, and the model was trained in preserved-thinking-history mode — meaning your client must send its reasoning back on every turn, not as an optimisation but as a requirement.
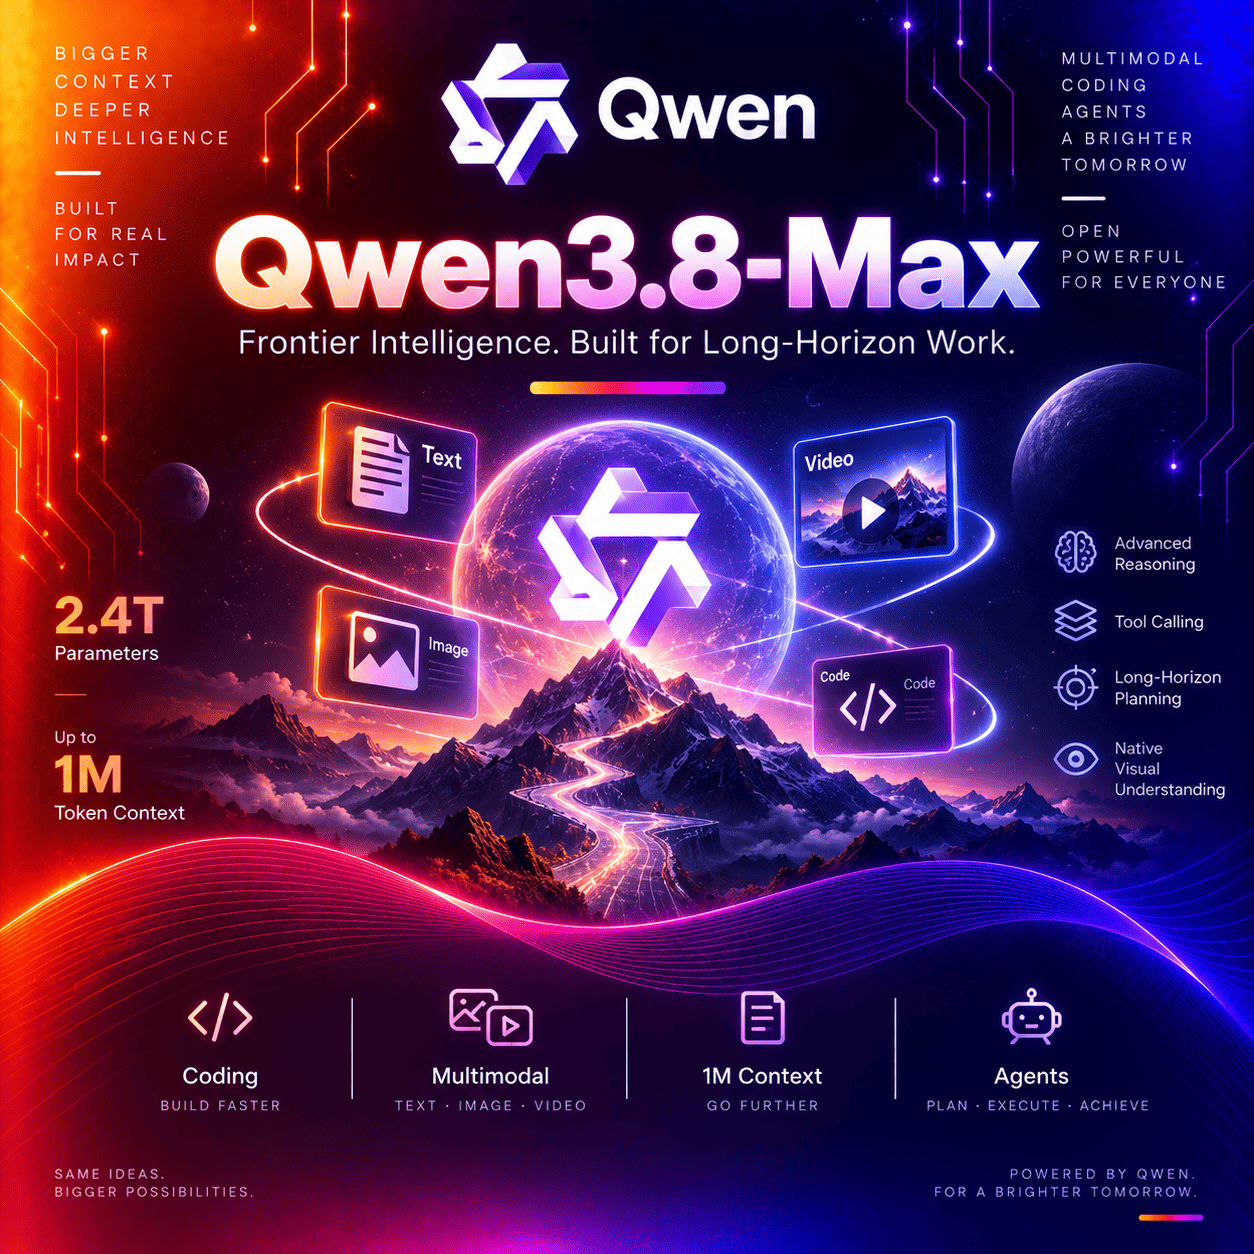
Qwen3.8-Max is Alibaba's flagship model and the complete form of the Qwen3.8 generation: a Mixture-of-Experts design with 2.4 trillion total parameters, 95 billion of which activate per token, running against a one-million-token context window with native text, image, and video input in a single endpoint. It reads PDFs of two hundred pages and more, and it uses vision throughout execution rather than only at the start — inspecting its own intermediate output, catching a misaligned interface or a wrong-facing object, and revising the plan. Thinking is hybrid: on by default, switchable off per request, and tunable across three depth levels, with reasoning traces that carry across turns so long agent loops keep their chain of thought.
The model prioritizes token efficiency and agentic inference at production scale, stretching what developers can achieve within limited token, latency, and serving-cost budgets.
Inkling-Small is a Mixture-of-Experts transformer with 276B total parameters, 12B active, trained on NVIDIA GB300 NVL72 systems. Like Inkling, it features native reasoning over audio and images, variable thinking effort
Gemma 4 31B is the largest dense model in Google DeepMind's open family, and its defining quality is how little it spends to think. Running a full intelligence evaluation consumed roughly 39 million output tokens — a fraction of what comparably-scoring reasoning models needed, because it reaches its conclusion rather than circling it. A 131,072-token context window takes entire codebases or large image sets in one prompt, with a vision encoder that accepts variable aspect ratios rather than forcing everything square. Thinking is configurable, function calling is native, and it runs on a workstation under Apache 2.0.
gpt-oss-120b is OpenAI's largest open-weight model and the first release of its kind since 2019. It carries roughly 117 billion parameters and activates about five per token, which is what lets a model of this capability run on a single 80GB card rather than a cluster. Reasoning effort is set as plain text in the system prompt across three levels, and the full chain of thought comes back unredacted — OpenAI published the accuracy-versus-length curve across all three settings, so the cost of deliberation is measured rather than implied. It ships under Apache 2.0 with no copyleft, no patent conditions, and no user ceiling.
Claude Opus 5 is Anthropic's model for complex agentic coding and enterprise work, and it thinks by default. Adaptive thinking means the model decides when and how much to reason on each turn rather than waiting to be told, with effort selectable across five levels. Its million-token context window is both the default and the maximum — there is no smaller variant and no long-context surcharge — and instruction following, tool calling, and reasoning stay consistent across the full window. The largest gains over the previous generation are in sustained multi-step analysis, long-horizon agentic work that completes features rather than leaving stubs, and converting additional effort into measurably better results.
Qwen3-ASR-0.6B is the compact model of the Qwen3-ASR family: multilingual language identification and speech recognition across 30 languages and 22 Chinese dialects, built on Qwen3-Omni. It targets an accuracy-efficiency trade-off with very high throughput, unified streaming/offline inference, and segment- and word-level timestamps.
Qwen3-ASR-1.7B is the flagship model of the Qwen3-ASR family: multilingual language identification and speech recognition across 30 languages and 22 Chinese dialects, built on Qwen3-Omni. It reaches state-of-the-art accuracy among open-source ASR models (competitive with strong commercial APIs), with unified streaming/offline inference and segment- and word-level timestamps.
Inkling is a general-purpose multimodal model that accepts text, image and audio inputs and generates text outputs.
Nemotron-3-Embed-8B is a multilingual text embedding model from NVIDIA, based on Ministral-3-8B, that maps text into 4096-dimensional dense vectors for retrieval and semantic similarity. Spanning 34 languages, it targets multilingual RAG and question-answering over large corpora and achieves state-of-the-art results on the RTEB leaderboard.
Nemotron-3-Embed-1B-NVFP4 is the NVFP4-quantized version of Nemotron-3-Embed-1B-BF16 — a multilingual text embedding model from NVIDIA that maps text into 2048-dimensional dense vectors for retrieval and semantic similarity. Optimized for NVIDIA Blackwell GPUs (e.g. RTX 6000 PRO, GB200), it retains near-BF16 quality (RTEB 72.0 vs 72.4) at a fraction of the memory and compute.
Nemotron-3-Embed-1B-BF16 is a compact multilingual text embedding model from NVIDIA, pruned and distilled from Ministral-3 to ~1B parameters, that maps text into 2048-dimensional dense vectors for retrieval and semantic similarity. Spanning 34 languages, it delivers state-of-the-art quality among similarly sized models for RAG and multilingual question-answering while keeping compute cost low.


